
Opus 5.5 vs Sonnet 5: the pricier model wrote my code for about half the cost
I priced five days of my coding-agent transcripts across four Claude models: 203 PRs and 411 reviewer agents. Opus 5.5 lists at twice Sonnet 5's price, yet cost about half as much per changed line once I compared like with like. Here is why, and what I changed.
Opus 5.5 lists at twice the price of Sonnet 5. In my coding agents it cost about half as much per line of code. It also replaced Fable 5.1 as my code reviewer, at about a third of the price.
This post is the data behind that switch: five days of my own Claude Code transcripts, priced at API list prices, with the parts that are proven kept apart from the parts that are only likely.
How I run agents
I work in waves. A lead model reads a list of GitHub issues and splits them into lanes that touch different files. Each lane gets an implementer agent that writes the code in its own git worktree and opens a PR. A separate reviewer agent then checks every PR: it runs the tests, breaks the code on purpose to see whether a test goes red, and checks the PR description's claims. Nothing merges until a reviewer passes it. A failed review ("needs-fix") goes back to the implementer for another round.
Between September 20 and 25 that produced 203 implementer PRs and 411 reviewer agents across four models. I pay a flat subscription, so the dollars below are API list prices, used as a measure of how much of my usage limit each agent burned.
| Model | Input $/M | Output $/M | Cached read $/M |
|---|---|---|---|
| Sonnet 5 | 2 | 10 | 0.20 |
| Opus 5 | 5 | 25 | 0.50 |
| Opus 5.5 | 4 | 20 | 0.20 |
| Fable 5.1 | 10 | 50 | 0.25 |
The last column is the one that matters, and the next section shows why.
Where the money actually goes
An agent doesn't pay for its work once. Every step is a new API call that sends the whole conversation again: the brief, every file it read, every test log. Most of that comes from the prompt cache, so each call is cheap, but an agent makes hundreds of them.
In one six-hour window on September 24, my agents used about $593 at list prices. 68% of that was cached reads, 22% cache writes and 10% output. Across 57 agents, cost tracked "number of calls × average context size" almost perfectly (correlation 0.99). The worst offenders were Sonnet implementers that ran 400–600 calls while their context grew to 600–970K tokens, because nothing compacted it before about 967K. Every one of those calls re-read the whole thing.
So the price per token matters less than you'd think. What matters is how many steps an agent takes and how much it carries through each one.
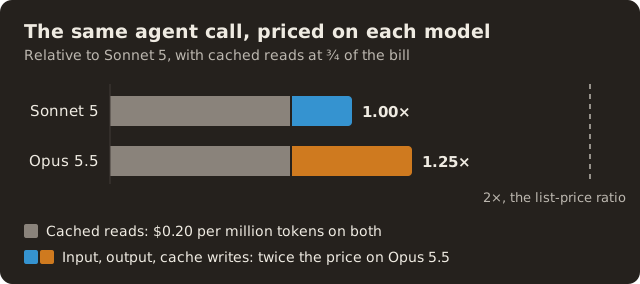
Cached reads cost the same $0.20 per million tokens on Opus 5.5 and Sonnet 5. Only input, output and cache writes cost twice as much on Opus. For my Sonnet implementers, cached reads were about three quarters of the bill (the median lane), so the same call costs only about 25% more on Opus 5.5, not twice as much.
Implementers: fewer steps beat a cheaper token
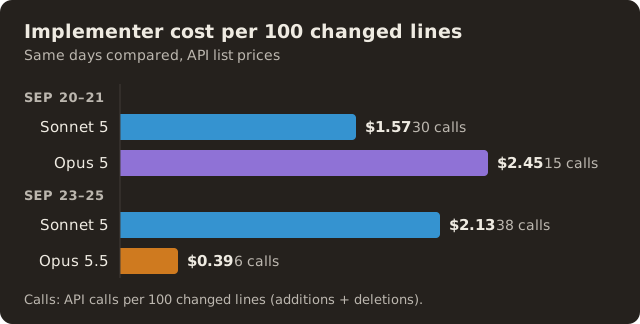
Opus 5 only ran on September 20–21 and Opus 5.5 only on September 23–25, so each is compared with Sonnet 5 on the same days:
| Days | Model | Cost per 100 changed lines | API calls per 100 lines |
|---|---|---|---|
| Sep 20–21 | Sonnet 5 | $1.57 | 30 |
| Sep 20–21 | Opus 5 | $2.45 | 15 |
| Sep 23–25 | Sonnet 5 | $2.13 | 38 |
| Sep 23–25 | Opus 5.5 | $0.39 | 6 |
"Changed lines" is additions plus deletions in the PR. The median PR was the same size for Sonnet 5 and Opus 5.5 (484 and 504 lines), so Opus isn't winning by writing more lines. Over all five days, per 100 changed lines, Opus 5.5 made 6 times fewer calls than Sonnet, read 10 times less context and wrote 3 times less output.
Opus 5 was not wasteful; its price was. Its prices are exactly 2.5 times Sonnet's on every kind of token, so at Sonnet's prices it would have cost $0.98 per 100 lines against Sonnet's $1.57. Opus 5.5 keeps that efficiency and drops the price.
The raw gap overstates it
The table says Opus 5.5 cost a fifth of Sonnet. That isn't a fair comparison, because I chose which tasks went to Opus, and I gave it mostly authentication and crypto work. So I compared units of work of the same size and kind, in the same repository and the same session. Measured that way, Opus 5.5 cost about 0.45 times what Sonnet did (plausible range 0.29–0.71).
That's still a big saving, and the more interesting part is where it comes from.
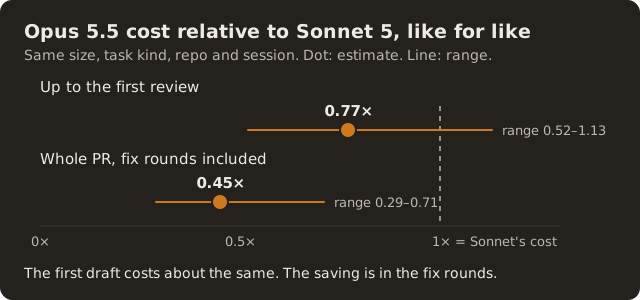
The first draft costs about the same. Up to the first review verdict, Opus 5.5 cost about 0.77 times Sonnet, and that range includes equal cost. Opus did bundle its work into fewer, longer shell commands: a median of 31 calls before the first review, against Sonnet's 97.
The saving is in the fix rounds. In the September 24 window, fix rounds were about 71% of implementer spend. A Sonnet implementer that had already grown a 900K context paid $5.60–6.40 for a small last-round fix, because it re-read everything to make it. Opus carried a smaller context (a median peak of 170K against Sonnet's 246K), and in the 5 Opus lanes of the fair split I describe at the end it needed a median of 2 review rounds against Sonnet's 3.
Most PRs fail their first review
On ordinary code, most PRs from every model failed their first review. Sonnet 5 and Opus 5 passed 12–20% of the time. In one six-hour window on September 24, all 20 PRs that changed production code failed their first review.
Opus 5.5's raw first-review pass rate looks great: 10 of 18. But almost all of those passes were auth work that I had routed to Opus and that Fable reviewed. On other code, Opus 5.5 passed 1 of 7, which is too few to say anything. Look at why PRs fail, and the model matters less: at least 7 of those 20 failures were tests that stayed green on broken code, or a PR description that claimed something untrue. I don't expect a smarter model to fix that, so I changed the process instead; it's too early to know whether that worked.
More reasoning effort cost more and bought nothing
Until this week, my implementers ran at whatever effort their lead used, so the past lanes cover several levels:
| Implementer | Effort | Cost per 100 changed lines | Passed first review |
|---|---|---|---|
| Sonnet 5 | medium | $1.72 | 8 of 64 (12%) |
| Sonnet 5 | high | $2.52 | 9 of 53 (17%) |
| Sonnet 5 | xhigh | $2.56 | 1 of 13 (8%) |
| Opus 5.5 | medium | $0.39 | 9 of 16 |
Sonnet at high effort cost 35–51% more per line than at medium, with no clear gain in review results. Opus 5.5 did its auth and crypto work at medium. This is observational (repositories ran at different efforts), so it's a signal, not proof. It was enough to stop me guessing effort up front.
Reviewers: Opus 5.5 against Fable 5.1
On the same kind of PR in the same days, with both priced at Opus 5.5's rates, a review round cost $1.36 on Opus 5.5 and $1.50 on Fable 5.1: about the same amount of work. At real list prices, Fable cost about 2.7 times more, and it was slower (a median of 9 minutes a round against 6.5).
Fable wasn't stricter either. On Sonnet-written code in the same days, it blocked 17 of 19 first submissions, and Opus 5.5 blocked 74 of 92. That is no real difference.
On the four PRs that both reviewed at the same time, each caught security bugs the other missed. One was a delete path that followed symbolic links: Fable caught it, and the Opus review running in parallel did not. So neither reviewer is complete on its own. Instead of paying 2.7 times more for a second opinion, I added that class of bug to the reviewer's checklist.
What I changed
- Opus 5.5 implements and reviews every diff. Fable stays paused.
- Medium effort by default. Reviews of production code run at xhigh, and reviews of auth, crypto, secrets, money, deploys and data migrations run at max. An implementer only moves up to xhigh for one fix round, when a PR's second failed review names a real behaviour defect.
- Compact at 400K tokens instead of about 967K. The single largest saving in the analysis: it caps how much every call has to re-read. Reviewers, which peaked at 277K in the window I measured, never hit it.
- A 1-hour cache for reviewers. Re-reviews usually arrive after the default 5-minute cache has expired, so the reviewer paid to rebuild its whole context.
- Proof for every test. Each test a PR adds or changes needs a line in the PR body naming the code change that turns it red. A PR without those lines goes back before any reviewer spends a token on it.
What this doesn't prove
It isn't a controlled experiment. I chose which tasks went to Opus, the sample is small (19 Opus 5.5 PRs), and list prices are a stand-in for subscription usage. I started a fair split, with every other lane on Opus 5.5 regardless of the task, and stopped it early: the like-for-like comparison and the token counts pointed the same way. Opus 5.5 was cheaper, probably around half, and at worst no more expensive.
One gap favours Opus in these numbers. In at least 3 of the 8 Opus PRs that failed their first review, the lead agent made the fix itself, so that fix's cost is missing from Opus's total. That happened in only 1 of 89 Sonnet cases.
The lesson I'd keep even if the model prices change next month: in agent work, you pay for steps and context, not for tokens. Measure calls and context per unit of work, and the right model is usually obvious.
Read next
Dev tricks, Part 1: The Importance of Code Formatting with Prettier
Are you tired of staring at messy, unformatted code that looks like it was written by a herd of chaotic monkeys? Fear not, because Prettier is here to save the day!
7 min read
Setting Up Your Own CI/CD Server with Drone CI
Running your own CI/CD with Drone CI on a $10 VPS. Docker Compose setup, pipeline config, GitHub integration — skip vendor lock-in, keep your builds private.
5 min read
How ChatGPT Can Help You Design System Architecture for Your Applications
ChatGPT as your architecture copilot: generate system diagrams, compare databases, spot security gaps before they ship. Real prompts that work.
5 min read

No spam. Unsubscribe anytime.